Coding agents are moving from autocomplete to action.
They read repositories, edit files, run shells, install packages, call APIs, access tools, and open pull requests. The change is not merely that AI writes more code. The change is that software organizations now have a new class of production actor.
Actors need boundaries, records, and independent checks.
A pull request is no longer the whole story
Traditional review begins with the diff. That works when a human’s local process is outside the system’s scope. An autonomous agent changes the boundary.
Two agents can produce the same diff through very different executions. One may read only relevant files and run targeted tests. Another may access secrets, reach an unapproved network destination, or modify generated artifacts before restoring them. Outcome review cannot reconstruct that behavior after the fact.
The system needs to preserve both what the agent produced and how the agent produced it.
The trust-layer architecture
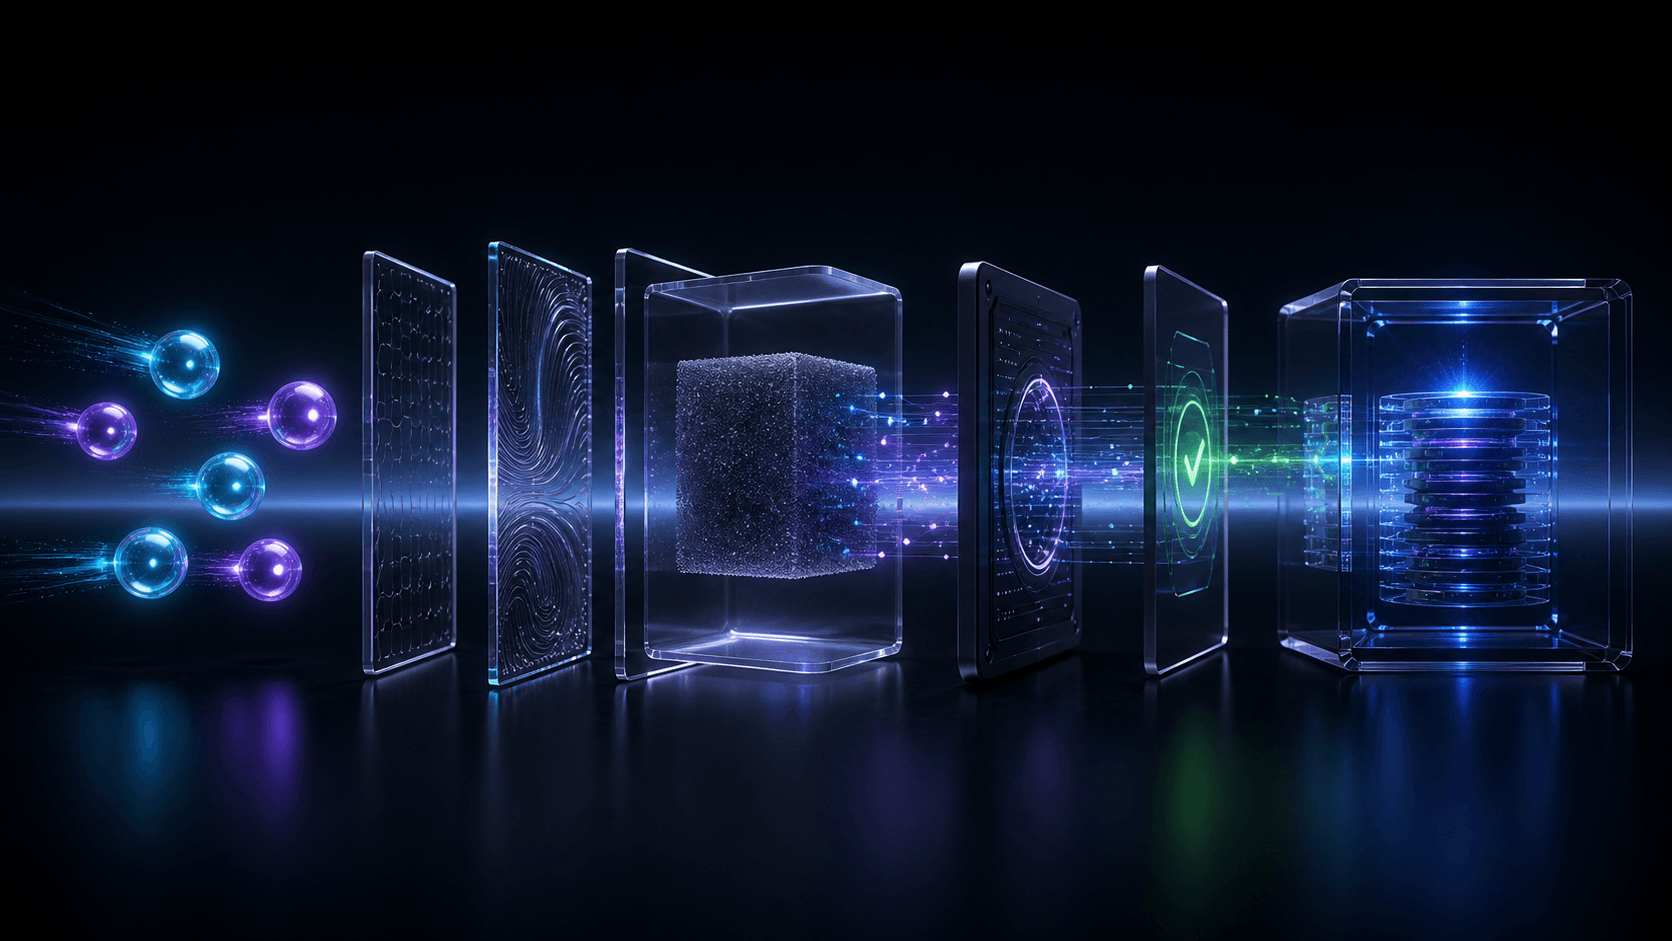
A practical architecture places an independent control plane between agents and engineering systems:
Coding agent
  → Agent gateway
  → Permission policy
  → Secure sandbox
  → Execution recorder
  → Git diff
  → Requirement extraction
  → Independent verification
  → Evidence ledger
  → Verdict
  → GitHub
Each layer has one job. The gateway normalizes agents. Policy decides what is allowed. The sandbox contains execution. The recorder preserves observed actions. Verification tests the result. The ledger connects everything into a durable record.
Normalize every action
Agent frameworks expose different events. The trust layer needs one portable vocabulary:
shell_commandfile_readfile_writenetwork_requestsecret_requesttool_callmcp_callsubagent_spawnpackage_install
Each event should include run identity, agent identity, declared intent, policy decision, timing, result, environment digest, and an evidence hash. This makes the execution inspectable across Codex, Claude Code, Copilot, Cursor, Grok, or an internal agent.
Policy should be explicit and local
“The agent is trusted” is not a permission model.
Define what the run can read, write, execute, and contact. Scope permissions to the task and repository. Record blocked attempts as evidence rather than silently discarding them. Escalation should require an explicit decision with a durable reason.
The goal is not to prevent capable agents from working. It is to make their authority legible.
Independent verification cannot be the same agent grading itself
The generating agent has context and momentum, but it also has an incentive to complete the task. Verification should use a separate process, prompt, or model boundary and should begin from the requirements.
The verifier can:
- run existing tests in a clean environment;
- generate adversarial or missing tests;
- inspect sensitive change paths;
- compare implementation with requirements;
- trace affected services and owners through the Engineering Graph;
- preserve unsupported requirements as explicit gaps.
Independence does not guarantee correctness. It reduces correlated failure and produces stronger evidence.
Evidence must survive the run
Transient agent logs are operational exhaust. An evidence ledger is a system of record.
Connect the run to the task, events, artifacts, diff, requirements, tests, findings, costs, and verdict. Hash important artifacts. Preserve source references. Make corrections additive so the history remains auditable.
This record becomes useful beyond compliance. It lets teams compare agent performance, investigate a regression, improve permissions, estimate verification cost, and understand which autonomous changes require the most human help.
Start with the decision, not the dashboard
The killer interface is a report inside the pull request:
Needs human review. Execution policy passed. The agent ran 31 commands, modified four files, and made one blocked network attempt. Three of four requirements are verified. Reused-token invalidation failed an independently generated test.
The detailed ledger remains available, but the summary tells the reviewer exactly why they are needed.
Trust should compound with use
The objective is not blanket autonomy. It is earned autonomy.
As the organization records more runs, requirements, tests, corrections, and outcomes, it can grant broader permissions to the workflows that repeatedly produce supported results. Risky or unfamiliar paths remain constrained.
That is a more durable future than choosing between “AI everywhere” and “AI nowhere.” The trust layer makes autonomy measurable, inspectable, and reversible.